

REMOVE Semantic Search Text Using Embeddings
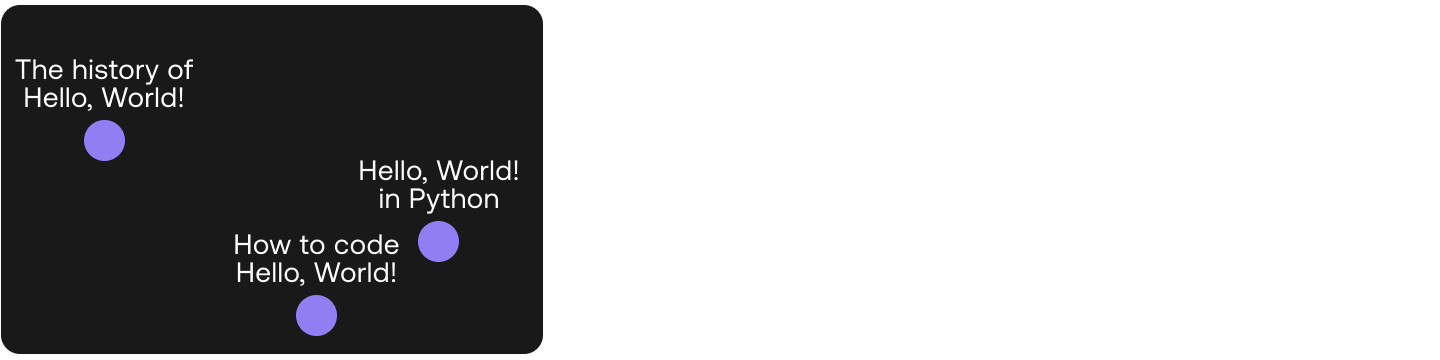 Over the next two chapters, you'll learn how to analyze text. The main ingredient is [embeddings](https://cohere.com/llmu), which as you learned in Module 2, are the bread and butter of Large Language Models. We'll use Cohere's [Embed](/api) endpoint to obtain embedding vectors for a dataset of questions. After this, we'll undertake two tasks: _Semantic Search_ and _Semantic Exploration_.
In this chapter we'll cover the first one, semantic search. Using embeddings, similarity, and nearest neighbors, you'll create a search model that will look for the answer to the given query in the dataset, just like you did in the Semantic Search chapter in Module 2.
Codelab
Section titled “Codelab”This chapter comes with a corresponding codelab, and we encourage you to follow it along as you read the chapter.
For the setup, please refer to the Setting Up chapter at the beginning of this module.
Introduction
Section titled “Introduction”The next area in language understanding is a broad one, which is analyzing text. Cohere’s Embed endpoint takes a piece of text and turns it into a vector embedding. Embeddings represent text in the form of numbers that capture its meaning and context.
This gives you the ability to turn unstructured text data into a structured form. It opens up ways to analyze and extract insights from them. Let’s take a look at a couple of examples.
Semantic Search
Section titled “Semantic Search”The first example is semantic search. There was a time when web search engines relied on keywords to match your search queries to the most relevant sites. But these days, you would be one frustrated user if that’s the kind experience you get, because these search engines are now able to capture semantic understanding of what you are looking for, beyond just keyword-matching.
Let’s build a simple semantic search engine. Here we have a list of 50 top web search terms about Hello, World! taken from a keyword tool. The following are a few examples:
df = pd.read_csv("hello-world-kw.csv", names=["search_term"])
df.head()| Keyword | |
|---|---|
| 0 | how to print hello world in python |
| 1 | what is hello world |
| 2 | how do you write hello world in an alert box |
| 3 | how to print hello world in java |
| 4 | how to write hello world in eclipse |
Let’s pretend that these search terms make up an FAQ database. Our job now, given a new query, is to ensure that the search engine returns the most similar FAQs.
The Embed endpoint is quite straightforward to use:
- Prepare input — The input is the list of text you want to embed.
- Define model settings — The model setting is just one: the model type. But it does make a difference to your task because bigger models generate embeddings with higher dimensions. We’ll use the default which is large.
- Generate output — The output is the corresponding embeddings for the input text.
The code looks like this:
def embed_text(texts):
  output = co.embed(
                model="large",
                texts=texts)
  embedding = output.embeddings

  return embedding
Now, given the FAQs, let’s try the search term “what is the history of hello world.” This is a search term whose keyword (i.e., “history”) doesn’t exist at all in the FAQ. Let’s see how the search fares.
First we get the embeddings of all the FAQs:
df["search_term_embeds"] = embed_text(df["search_term"].tolist())
embeds = np.array(df["search_term_embeds"].tolist())
And then get the embeddings of the new query:
new_query = "what is the history of hello world"
new_query_embeds = embed_text(new_query)
Next, we compare the similarity of the embeddings of the new query with each of the embeddings of the FAQs. There are many options to do this, and one option is using cosine similarity. We’ll utilize scikit-learn’s library to perform this.
The steps are:
- Calculate similarity between the new query with each of the FAQs
- Sort the FAQs by descending order in similarity (the most similar first)
- Show the top FAQs with the highest similarity to the new query
The code is shown below:
from sklearn.metrics.pairwise import cosine_similarity

def get_similarity(target,candidates):
  # Turn list into array
  candidates = np.array(candidates)
  target = np.expand_dims(np.array(target),axis=0)

  # Calculate cosine similarity
  sim = cosine_similarity(target,candidates)
  sim = np.squeeze(sim).tolist()

  # Sort by descending order in similarity
  sim = list(enumerate(sim))
  sim = sorted(sim, key=lambda x:x[1], reverse=True)

  # Return similarity scores
  return sim

similarity = get_similarity(new_query_embeds,embeds)

# Show the top 5 FAQs with the highest similarity to the new query
for idx,score in similarity[:5]:
  print(f"Similarity: {score:.2f};", df.iloc[idx]["search_term"])
And the output we get is:
New query:
what is the history of hello world

Similar queries:
Similarity: 0.89; how did hello world originate
Similarity: 0.87; where did hello world come from
Similarity: 0.82; what is hello world
Similarity: 0.73; why is hello world so famous
Similarity: 0.70; why hello world
It works! Notice that the top terms are indeed the closest in meaning to the search term (about the history and origin of Hello, World!) even though they use different kinds of words.
Conclusion
Section titled “Conclusion”In this chapter you learned how to use embeddings for a very important AI task: Semantic Search. Follow along to the next chapter, where you'll learn to use embeddings for another very important task: Semantic Exploration.